
zihao commited on
Commit ·
1908da4
1
Parent(s): 080541b
[init] initial the README.md
Browse files
README.md
CHANGED
|
@@ -1,3 +1,80 @@
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
|
|
|
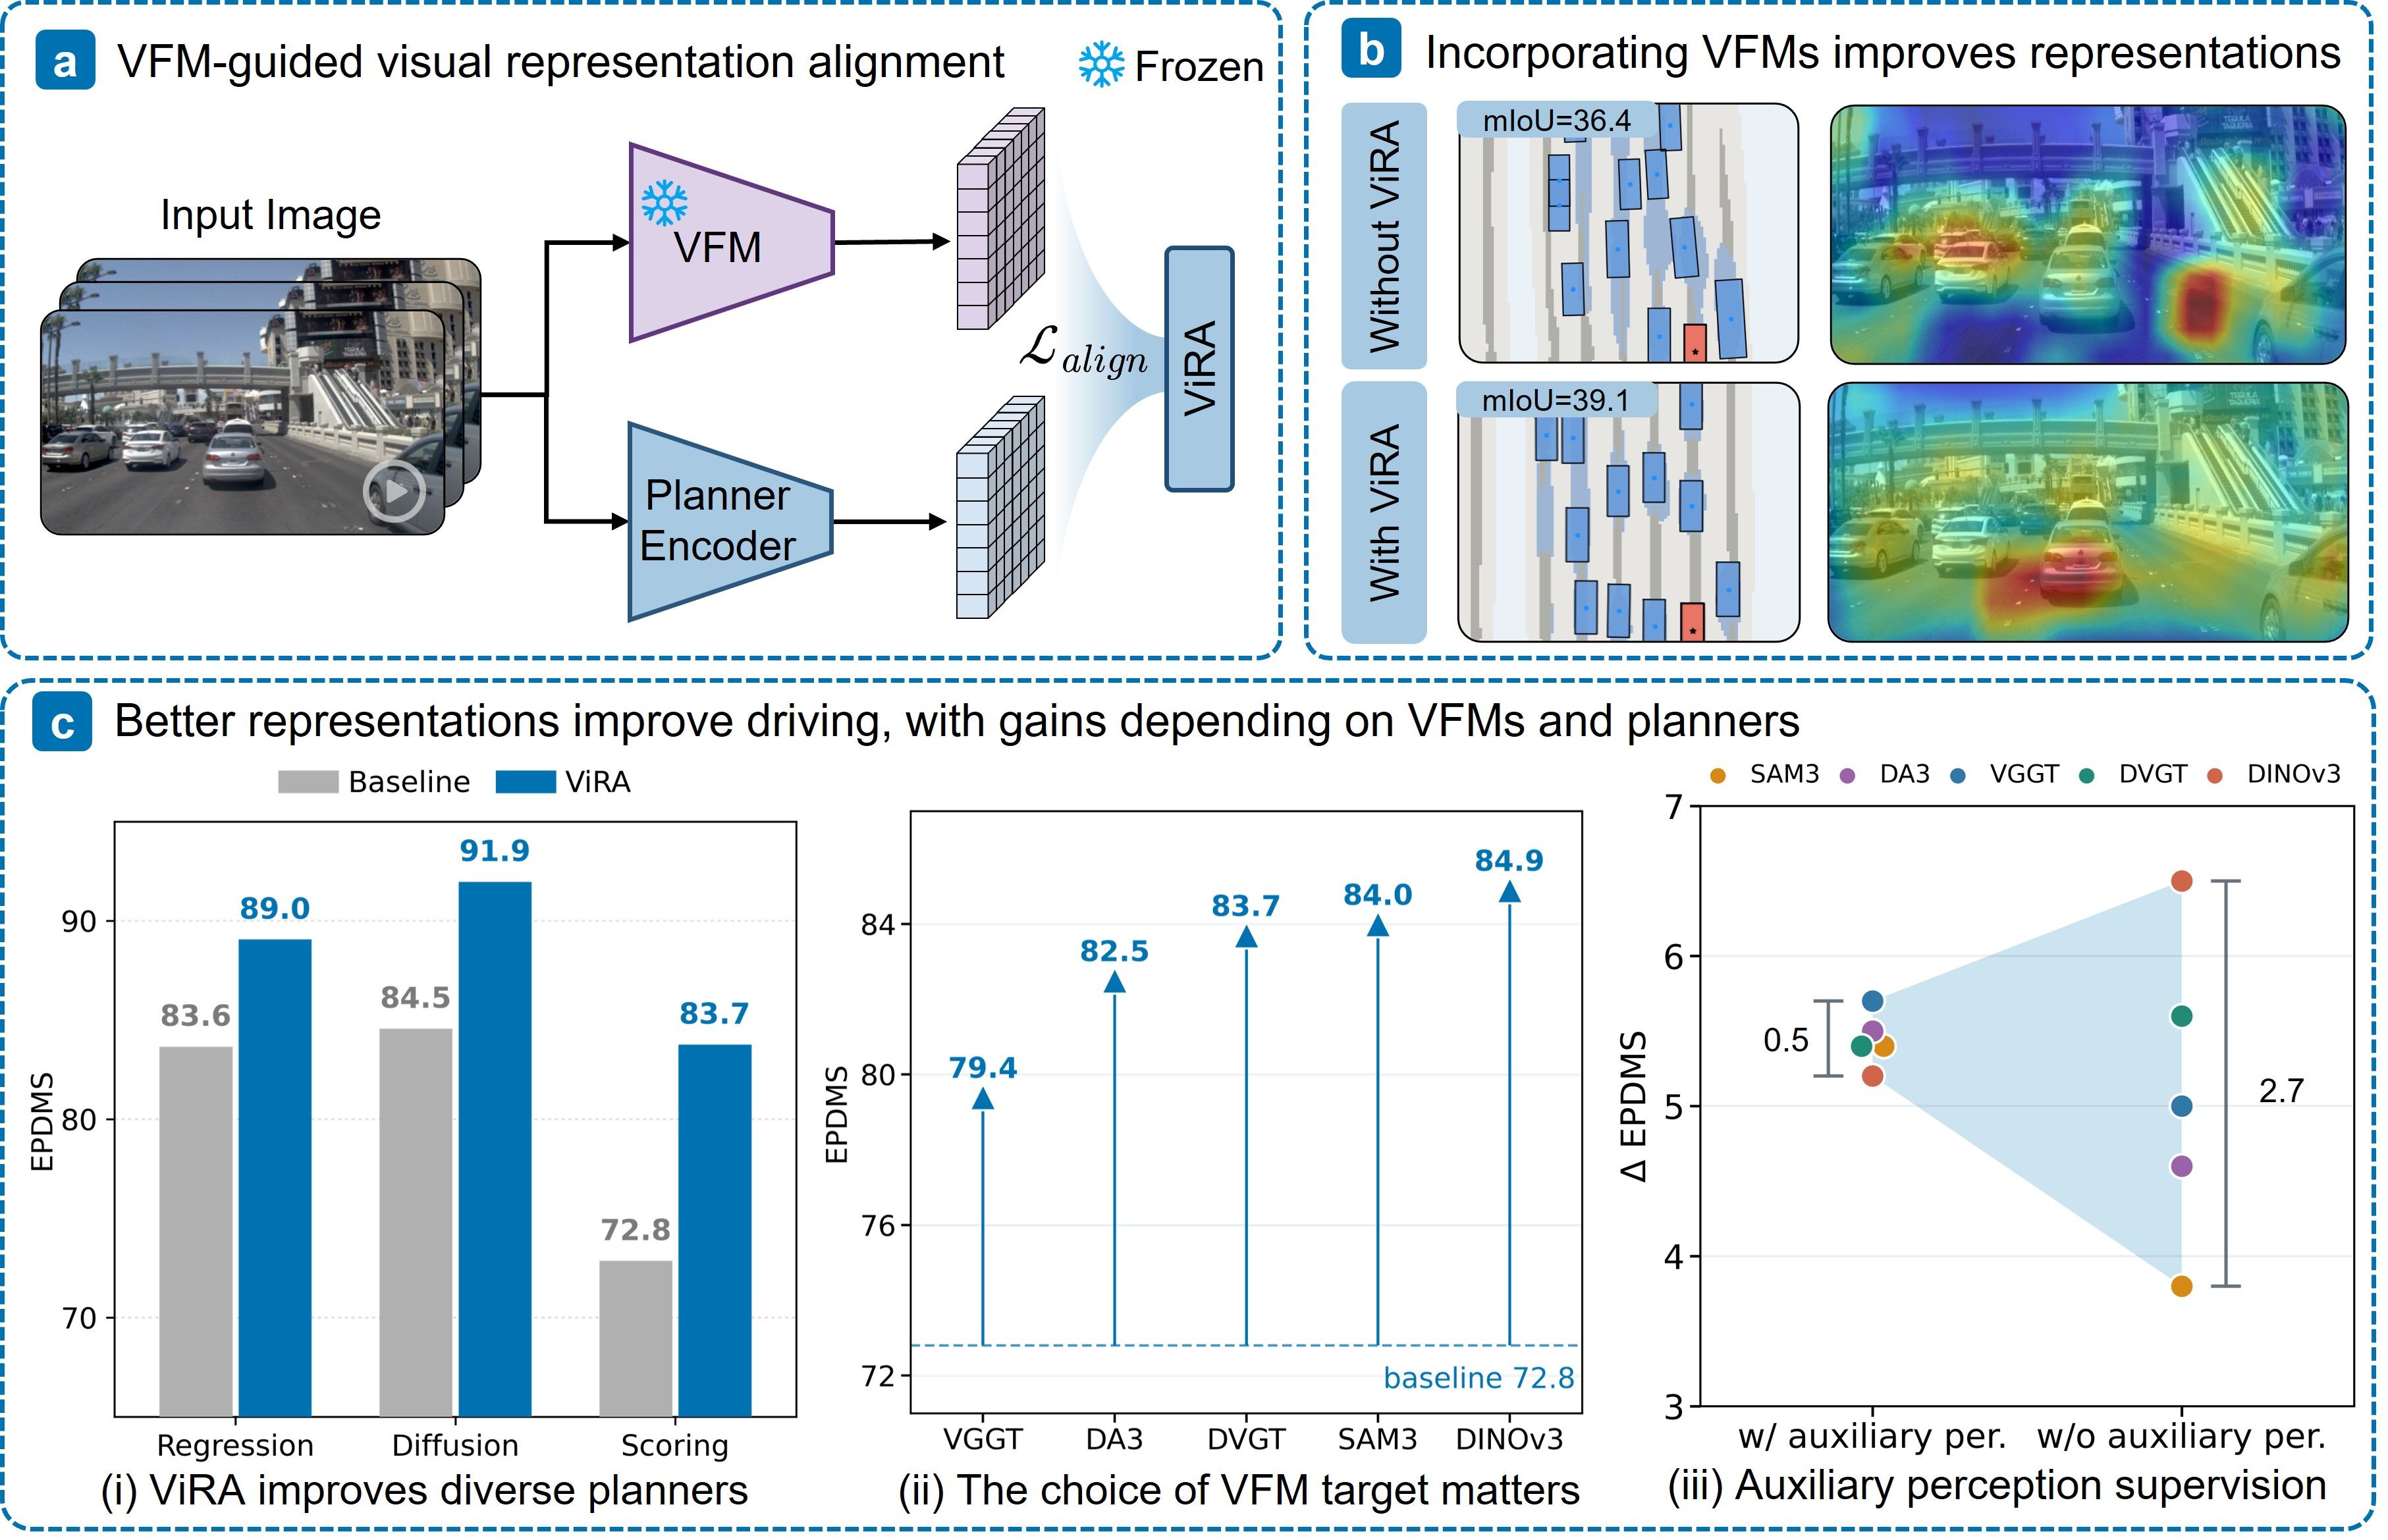
|
|
|
|
|
|
|
|
|
|
|
|
| 3 |
---
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
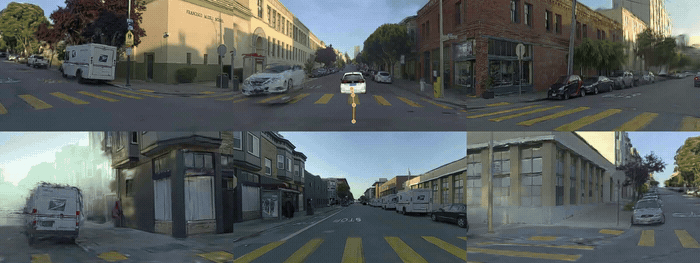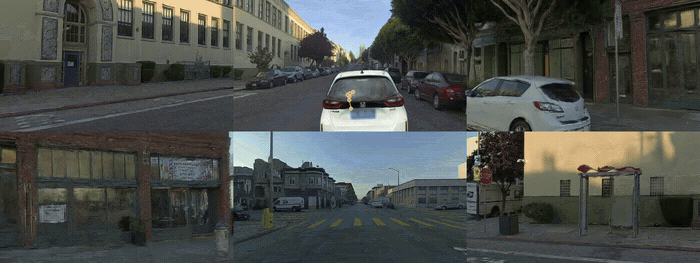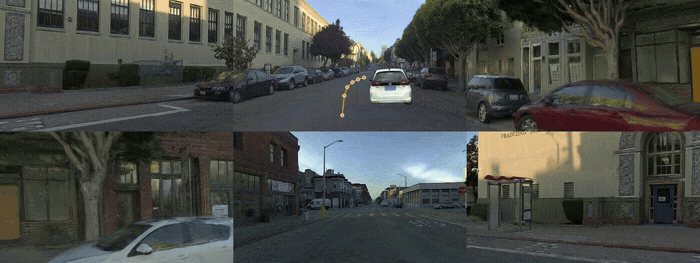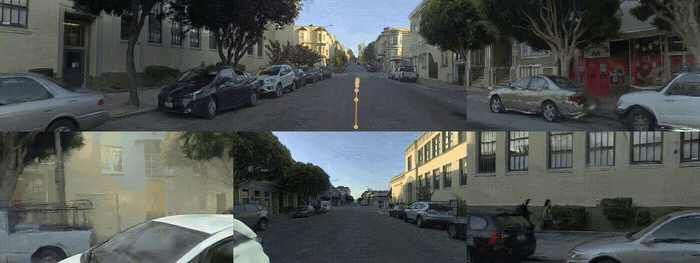
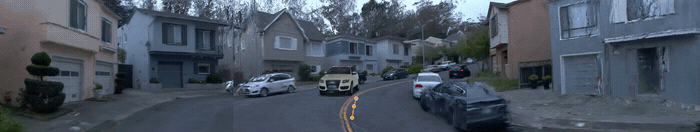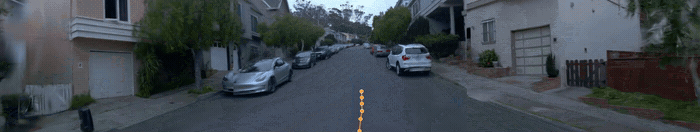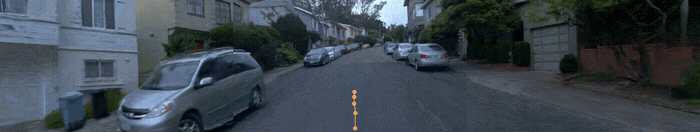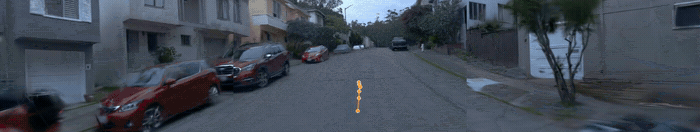
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
---
|
| 2 |
license: apache-2.0
|
| 3 |
+
tags:
|
| 4 |
+
- robotics
|
| 5 |
+
- autonomous-driving
|
| 6 |
+
- computer-vision
|
| 7 |
+
- end-to-end
|
| 8 |
---
|
| 9 |
+
|
| 10 |
+
# Do Better Visual Representations Always Lead to Better End-to-End Autonomous Driving?
|
| 11 |
+
|
| 12 |
+
[**Paper**](https://arxiv.org/abs/2610.09695v1) | [**Project Page**](https://opendrivelab.com/ViRA/) | [**GitHub Repository**](https://github.com/OpenDriveLab/ViRA)
|
| 13 |
+
|
| 14 |
+
Visual foundation models (VFMs) are increasingly integrated into end-to-end autonomous driving, yet it remains unclear when these representations improve driving performance. **ViRA** is a planner-agnostic visual representation alignment framework: during training it aligns planner features with a frozen VFM, while the deployed planner architecture and inference cost stay unchanged.
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
## Findings
|
| 19 |
+
|
| 20 |
+
The study is organized around three empirical findings:
|
| 21 |
+
|
| 22 |
+
1. **Consistent driving gains:** VFM-guided visual representations improve driving across regression, diffusion, and scoring planners. The gains extend to zero-shot closed-loop evaluation.
|
| 23 |
+
2. **Target selection matters:** Different VFM targets yield different planning gains for the same planner. Alignment to another VFM can further benefit planners that already use a pre-trained VFM encoder.
|
| 24 |
+
3. **Supervision changes sensitivity:** Auxiliary perception supervision narrows the EPDMS spread across five VFM targets from 2.7 to 0.5 points, and can compensate for a less effective target.
|
| 25 |
+
|
| 26 |
+
## Performance
|
| 27 |
+
|
| 28 |
+
Guided by these findings, **ViRA-Diffusion** aligns a diffusion planner to DINOv3 and is trained without auxiliary perception supervision. It reaches **92.3 EPDMS** on NAVSIM v2 navtest, exceeding the recent methods in our comparison by at least 1.9 points.
|
| 29 |
+
|
| 30 |
+
The same alignment improves three camera-only planners. On NAVSIM v2 navtest, EPDMS rises by **+5.4** for TransFuser (83.6 → 89.0), **+7.4** for DiffusionDrive (84.5 → 91.9), and **+10.9** for Rap\* (72.8 → 83.7). On the challenging navhard split, Rap\*-ViRA gains **+16.4** EPDMS. Checkpoints trained only on NAVSIM also improve zero-shot closed-loop HD-Score on HUGSIM.
|
| 31 |
+
|
| 32 |
+
| Method | Decoder | NAVSIM v2 navtest EPDMS | NAVSIM v2 navhard EPDMS | HUGSIM HD-Score |
|
| 33 |
+
| --- | --- | --- | --- | --- |
|
| 34 |
+
| TransFuser | Regression | 83.6 | 27.6 | 22.1 |
|
| 35 |
+
| TransFuser-ViRA | Regression | **89.0** (+5.4) | **31.7** (+4.1) | **24.8** (+2.7) |
|
| 36 |
+
| DiffusionDrive | Diffusion | 84.5 | 30.5 | 22.2 |
|
| 37 |
+
| DiffusionDrive-ViRA | Diffusion | **91.9** (+7.4) | **35.8** (+5.3) | **28.6** (+6.4) |
|
| 38 |
+
| Rap\* | Scoring | 72.8 | 32.8 | 7.3 |
|
| 39 |
+
| Rap\*-ViRA | Scoring | **83.7** (+10.9) | **49.2** (+16.4) | **10.3** (+3.0) |
|
| 40 |
+
|
| 41 |
+
| Method | NAVSIM v2 navtest EPDMS |
|
| 42 |
+
| --- | --- |
|
| 43 |
+
| Epona | 85.1 |
|
| 44 |
+
| DiffusionDriveV2 | 87.5 |
|
| 45 |
+
| Latent-WAM | 89.3 |
|
| 46 |
+
| DriveFuture | 89.9 |
|
| 47 |
+
| SparseDriveV2 | 90.1 |
|
| 48 |
+
| Discrete-WAM | 90.4 |
|
| 49 |
+
| **ViRA-Diffusion** | **92.3** |
|
| 50 |
+
|
| 51 |
+
Camera-only. Rap\* is our reimplementation with a different backbone and without the original data augmentation. HUGSIM is zero-shot: planners are trained only on NAVSIM. ViRA-Diffusion is DiffusionDrive trained with DINOv3 alignment and without auxiliary perception supervision. DiffusionDrive-ViRA (91.9) and ViRA-Diffusion (92.3) are distinct configurations.
|
| 52 |
+
|
| 53 |
+
## License
|
| 54 |
+
|
| 55 |
+
All content in this repository is licensed under the [Apache 2.0](https://www.apache.org/licenses/LICENSE-2.0) license.
|
| 56 |
+
|
| 57 |
+
|
| 58 |
+
## HUGSIM Closed-loop Visualization
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
|
| 62 |
+
**(a) Car following: the lead vehicle brakes suddenly**
|
| 63 |
+
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
**(b) Oncoming traffic: other vehicles enter the current driving area**
|
| 67 |
+
|
| 68 |
+
## Citation
|
| 69 |
+
|
| 70 |
+
If you find ViRA useful in your research, please consider citing:
|
| 71 |
+
|
| 72 |
+
```bibtex
|
| 73 |
+
@article{zhang2026vira,
|
| 74 |
+
title={Do Better Visual Representations Always Lead to Better End-to-End Autonomous Driving?},
|
| 75 |
+
author={Zhang, Zihao and Tian, Haochen and Li, Tianyu and Jing, Changhui and He, Jingliang and Ye, Naisheng and Pu, Ziyuan and Yang, Zhenjie},
|
| 76 |
+
journal={arXiv preprint arXiv:2610.09695},
|
| 77 |
+
year={2026},
|
| 78 |
+
url={https://arxiv.org/abs/2610.09695}
|
| 79 |
+
}
|
| 80 |
+
```
|